Archive for Laplace approximation

efficient approximate Bayesian inference for models with intractable likelihood

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , on July 6, 2015 by xi'an

Awalé board on my garden table, March 15, 2013Dalhin, Villani [Mattias, not Cédric] and Schön arXived a paper this week with the above title. The type of intractable likelihood they consider is a non-linear state-space (HMM) model and the SMC-ABC they propose is based on an optimised Laplace approximation. That is, replacing the posterior distribution on the parameter θ with a normal distribution obtained by a Taylor expansion of the log-likelihood. There is no obvious solution for deriving this approximation in the case of intractable likelihood functions and the authors make use of a Bayesian optimisation technique called Gaussian process optimisation (GPO). Meaning that the Laplace approximation is the Laplace approximation of a surrogate log-posterior. GPO is a Bayesian numerical method in the spirit of the probabilistic numerics discussed on the ‘Og a few weeks ago. In the current setting, this means iterating three steps

  1. derive an approximation of the log-posterior ξ at the current θ using SMC-ABC
  2. construct a surrogate log-posterior by a Gaussian process using the past (ξ,θ)’s
  3. determine the next value of θ

In the first step, a standard particle filter cannot be used to approximate the observed log-posterior at θ because the conditional density of observed given latent is intractable. The solution is to use ABC for the HMM model, in the spirit of many papers by Ajay Jasra and co-authors. However, I find the construction of the substitute model allowing for a particle filter very obscure… (A side effect of the heat wave?!) I can spot a noisy ABC feature in equation (7), but am at a loss as to how the reparameterisation by the transform τ is compatible with the observed-given-latent conditional being unavailable: if the pair (x,v) at time t has a closed form expression, so does (x,y), at least on principle, since y is a deterministic transform of (x,v). Another thing I do not catch is why having a particle filter available prevent the use of a pMCMC approximation.

The second step constructs a Gaussian process posterior on the log-likelihood, with Gaussian errors on the ξ’s. The Gaussian process mean is chosen as zero, while the covariance function is a Matérn function. With hyperparameters that are estimated by maximum likelihood estimators (based on the argument that the marginal likelihood is available in closed form). Turning the approach into an empirical Bayes version.

The next design point in the sequence of θ’s is the argument of the maximum of a certain acquisition function, which is chosen here as a sort of maximum regret associated with the posterior predictive associated with the Gaussian process. With possible jittering. At this stage, it reminded me of the Gaussian process approach proposed by Michael Gutmann in his NIPS poster last year.

Overall, the method is just too convoluted for me to assess its worth and efficiency without a practical implementation to… practice upon, for which I do not have time! Hence I would welcome any comment from readers having attempted such implementations. I also wonder at the lack of link with Simon Wood‘s Gaussian approximation that appeared in Nature (2010) and was well-discussed in the Read Paper of Fearnhead and Prangle (2012).
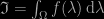
density normalization for MCMC algorithms

Posted in Statistics, University life with tags , , , , , , , , on November 6, 2014 by xi'an

Another paper addressing the estimation of the normalising constant and the wealth of available solutions just came out on arXiv, with the full title of “Target density normalization for Markov chain Monte Carlo algorithms“, written by Allen Caldwell and Chang Liu. (I became aware of it by courtesy of Ewan Cameron, as it appeared in the physics section of arXiv. It is actually a wee bit annoying that papers in the subcategory “Data Analysis, Statistics and Probability” of physics do not get an automated reposting on the statistics lists…)

In this paper, the authors compare three approaches to the problem of finding

\mathfrak{I} = \int_\Omega f(\lambda)\,\text{d}\lambda

when the density f is unormalised, i.e., in more formal terms, when f is proportional to a probability density (and available):

  1. an “arithmetic mean”, which is an importance sampler based on (a) reducing the integration volume to a neighbourhood ω of the global mode. This neighbourhood is chosen as an hypercube and the importance function turns out to be the uniform over this hypercube. The corresponding estimator is then a rescaled version of the average of f over uniform simulations in ω.
  2.  an “harmonic mean”, of all choices!, with again an integration over the neighbourhood ω of the global mode in order to avoid the almost sure infinite variance of harmonic mean estimators.
  3. a Laplace approximation, using the target at the mode and the Hessian at the mode as well.

The paper then goes to comparing those three solutions on a few examples, demonstrating how the diameter of the hypercube can be calibrated towards a minimum (estimated) uncertainty. The rather anticlimactic conclusion is that the arithmetic mean is the most reliable solution as harmonic means may fail in larger dimension and more importantly fail to signal its failure, while Laplace approximations only approximate well quasi-Gaussian densities…

What I find most interesting in this paper is the idea of using only one part of the integration space to compute the integral, even though it is not exactly new. Focussing on a specific region ω has pros and cons, the pros being that the reduction to a modal region reduces needs for absolute MCMC convergence and helps in selecting alternative proposals and also prevents from the worst consequences of using a dreaded harmonic mean, the cons being that the region needs be well-identified, which means requirements on the MCMC kernel, and that the estimate is a product of two estimates, the frequency being driven by a Binomial noise.  I also like very much the idea of calibrating the diameter Δof the hypercube ex-post by estimating the uncertainty.

As an aside, the paper mentions most of the alternative solutions I just presented in my Monte Carlo graduate course two days ago (like nested or bridge or Rao-Blackwellised sampling, including our proposal with Darren Wraith), but dismisses them as not “directly applicable in an MCMC setting”, i.e., without modifying this setting. I unsurprisingly dispute this labelling, both because something like the Laplace approximation requires extra-work on the MCMC output (and once done this work can lead to advanced Laplace methods like INLA) and because other methods could be considered as well (for instance, bridge sampling over several hypercubes). As shown in the recent paper by Mathieu Gerber and Nicolas Chopin (soon to be discussed at the RSS!), MCqMC has also become a feasible alternative that would compete well with the methods studied in this paper.

Overall, this is a paper that comes in a long list of papers on constant approximations. I do not find the Markov chain of MCMC aspect particularly compelling or specific, once the effective sample size is accounted for. It would be nice to find generic ways of optimising the visit to the hypercube ω and to estimate efficiently the weight of ω. The comparison is solely run over examples, but they all rely on a proper characterisation of the hypercube and the ability to simulate efficiently f over that hypercube.