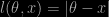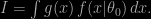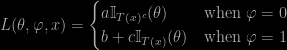Archive for loss functions

a general framework for updating belief functions [reply from the authors]

Posted in Statistics, University life with tags , , , , , , on July 16, 2013 by xi'an

Here is the reply by Chris and Steve about my comments from yesterday:

Thanks to Christian for the comments and feedback on our paper “A General Framework for Updating Belief Distributions“. We agree with Christian that starting with a summary statistic, or statistics, is an anchor for inference or learning, providing direction and guidance for models, avoiding the alternative vague notion of attempting to model a complete data set. The latter idea has dominated the Bayesian methodology for decades, but with the advent of large and complex data sets, this is becoming increasingly challenging, if not impossible.

However, in order to do work with statistics of interest, we need to find a framework in which this direct approach can be supported by a learning strategy when the formal use of Bayes theorem is not applicable. We achieve this in the paper for a general class of loss functions, which connect observations with a target of interest. A point raised by Christian is how arbitrary these loss functions are. We do not see this at all; for if a target has been properly identified then the most primitive construct between observations informing about a target and the target would come in the form of a loss function. One should always be able to assess the loss of ascertaining a value of \theta as an action and providing the loss in the presence of observation x. The question to be discussed is whether loss functions are objective, as in the case of the median loss,

l(\theta,x)=|\theta-x|

or subjective, in the case of the choice between loss functions for estimating a location of a distribution; mean, median or mode? But our work is situated in the former position.

Previous work on loss functions, mostly in the classical literature, has spent a lot of space working out what are optimal loss functions for targets of interest. We are not really dealing with novel targets and so we can draw on the classic literature here. The work can be thought of as the Bayesian version of the M-estimator and associated ideas. In this respect we are dealing with two loss functions for updating belief distributions, one for the data, which we have just discussed, and one for the prior information, which, due to coherence principles, must be the Kullback-Leibler divergence. This raises the thorny issue of how to calibrate the two loss functions. We discuss this in the paper.

To then deal with the statistic problem, mentioned at the start of this discussion, we have found a nice way to proceed by using the loss function l(\theta,x)=-\log f(x|\theta). How this loss function, combined with the use of the exponential family, can be used to estimate functionals of the type
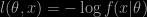
I=\int g(x)\,f_0(x)\, dx

is provided in the Walker talk at Bayes 250 in London, titled “The Misspecified Bayesian”, since the “model” f(x|\theta) is designed to be misspecified, a tool to estimate and learn about I only. The basic idea is to evaluate I by ensuring that we learn about the \theta_0 for which

I=\int g(x)\,f(x|\theta_0)\, dx.

This is the story of the background, we would now like to pick up in more detail on three important points that you raise in your post:

  1. The arbitrariness in selecting the loss function.
  2. The relative weighting of loss-to-data vs. loss-to-prior.
  3. The selection of the loss in the M-free case.

In the absence of complete knowledge of the data generating mechanism, i.e. outside of M-closed,

  1. We believe the statistician should weigh up the relative arbitrariness in selecting a loss function targeting the statistic of interest versus the arbitrariness of selecting a misspecified model, known not to be true, for the complete data generating mechanism. There is a wealth of literature on how to select optimal loss functions that target specific statistics, e.g. Hüber (2009) provides a comprehensive overview of how this should be done. As far as we are aware, we know of no formal procedures (that do not rely on loss functions) to select a false sampling distribution f(x|\theta) for the whole of x; see Key, Pericchi and Smith (1999).
  2. The relative weighting of loss-to-data vs. loss-to-prior. This is an interesting open problem. Our framework shows in the absence of M-closed or the use of self-information loss that the analyst must select this weighting. In our paper we suggest some default procedures. We have nowhere claimed these were “correct”. You raise concerns regards parameterisation and we agree with you that care is needed, but many of these issues equally hold for existing “Objective” or “Default” Bayes procedures, such as unit-information priors.
  3. The selection of the loss in M-free. You say “….there is no optimal choice for the substitute to the loss function…”. We disagree. Our approach is to select an established loss function that directly targets the statistic of interest, and elicit prior beliefs directly on the unknown value of this statistic. There is no notion here of a a pseudo-likelihood or where this converges to.

Thank you again to Christian for his critical observations!
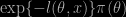
a general framework for updating belief functions

Posted in Books, Statistics, University life with tags , , , , , , , , , on July 15, 2013 by xi'an

Pier Giovanni Bissiri, Chris Holmes and Stephen Walker have recently arXived the paper related to Sephen’s talk in London for Bayes 250. When I heard the talk (of which some slides are included below), my interest was aroused by the facts that (a) the approach they investigated could start from a statistics, rather than from a full model, with obvious implications for ABC, & (b) the starting point could be the dual to the prior x likelihood pair, namely the loss function. I thus read the paper with this in mind. (And rather quickly, which may mean I skipped important aspects. For instance, I did not get into Section 4 to any depth. Disclaimer: I wasn’t nor is a referee for this paper!)

The core idea is to stick to a Bayesian (hardcore?) line when missing the full model, i.e. the likelihood of the data, but wishing to infer about a well-defined parameter like the median of the observations. This parameter is model-free in that some degree of prior information is available in the form of a prior distribution. (This is thus the dual of frequentist inference: instead of a likelihood w/o a prior, they have a prior w/o a likelihood!) The approach in the paper is to define a “posterior” by using a functional type of loss function that balances fidelity to prior and fidelity to data. The prior part (of the loss) ends up with a Kullback-Leibler loss, while the data part (of the loss) is an expected loss wrt to l(THETASoEUR,x), ending up with the definition of a “posterior” that is

\exp\{ -l(\theta,x)\} \pi(\theta)

the loss thus playing the role of the log-likelihood.

I like very much the problematic developed in the paper, as I think it is connected with the real world and the complex modelling issues we face nowadays. I also like the insistence on coherence like the updating principle when switching former posterior for new prior (a point sorely missed in this book!) The distinction between M-closed M-open, and M-free scenarios is worth mentioning, if only as an entry to the Bayesian processing of pseudo-likelihood and proxy models. I am however not entirely convinced by the solution presented therein, in that it involves a rather large degree of arbitrariness. In other words, while I agree on using the loss function as a pivot for defining the pseudo-posterior, I am reluctant to put the same faith in the loss as in the log-likelihood (maybe a frequentist atavistic gene somewhere…) In particular, I think some of the choices are either hard or impossible to make and remain unprincipled (despite a call to the LP on page 7).  I also consider the M-open case as remaining unsolved as finding a convergent assessment about the pseudo-true parameter brings little information about the real parameter and the lack of fit of the superimposed model. Given my great expectations, I ended up being disappointed by the M-free case: there is no optimal choice for the substitute to the loss function that sounds very much like a pseudo-likelihood (or log thereof). (I thought the talk was more conclusive about this, I presumably missed a slide there!) Another great expectation was to read about the proper scaling of the loss function (since L and wL are difficult to separate, except for monetary losses). The authors propose a “correct” scaling based on balancing both faithfulness for a single observation, but this is not a completely tight argument (dependence on parametrisation and prior, notion of a single observation, &tc.)

The illustration section contains two examples, one of which is a full-size or at least challenging  genetic data analysis. The loss function is based on a logistic  pseudo-likelihood and it provides results where the Bayes factor is in agreement with a likelihood ratio test using Cox’ proportional hazard model. The issue about keeping the baseline function as unkown reminded me of the Robbins-Wasserman paradox Jamie discussed in Varanasi. The second example offers a nice feature of putting uncertainties onto box-plots, although I cannot trust very much the 95%  of the credibles sets. (And I do not understand why a unique loss would come to be associated with the median parameter, see p.25.)

Watch out: Tomorrow’s post contains a reply from the authors!

beware, nefarious Bayesians threaten to take over frequentism using loss functions as Trojan horses!

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on November 12, 2012 by xi'an

“It is not a coincidence that textbooks written by Bayesian statisticians extol the virtue of the decision-theoretic perspective and then proceed to present the Bayesian approach as its natural extension.” (p.19)

“According to some Bayesians (see Robert, 2007), the risk function does represent a legitimate frequentist error because it is derived by taking expectations with respect to [the sampling density]. This argument is misleading for several reasons.” (p.18)

During my R exam, I read the recent arXiv posting by Aris Spanos on why “the decision theoretic perspective misrepresents the frequentist viewpoint”. The paper is entitled “Why the Decision Theoretic Perspective Misrepresents Frequentist Inference: ‘Nuts and Bolts’ vs. Learning from Data” and I found it at the very least puzzling…. The main theme is the one caricatured in the title of this post, namely that the decision-theoretic analysis of frequentist procedures is a trick brought by Bayesians to justify their own procedures. The fundamental argument behind this perspective is that decision theory operates in a “for all θ” referential while frequentist inference (in Spanos’ universe) is only concerned by one θ, the true value of the parameter. (Incidentally, the “nuts and bolt” refers to the only case when a decision-theoretic approach is relevant from a frequentist viewpoint, namely in factory quality control sampling.)

“The notions of a risk function and admissibility are inappropriate for frequentist inference because they do not represent legitimate error probabilities.” (p.3)

“An important dimension of frequentist inference that has not been adequately appreciated in the statistics literature concerns its objectives and underlying reasoning.” (p.10)

“The factual nature of frequentist reasoning in estimation also brings out the impertinence of the notion of admissibility stemming from its reliance on the quantifier ‘for all’.” (p.13)

One strange feature of the paper is that Aris Spanos seems to appropriate for himself the notion of frequentism, rejecting the choices made by (what I would call frequentist) pioneers like Wald, Neyman, “Lehmann and LeCam [sic]”, Stein. Apart from Fisher—and the paper is strongly grounded in neo-Fisherian revivalism—, the only frequentists seemingly finding grace in the eyes of the author are George Box, David Cox, and George Tiao. (The references are mostly to textbooks, incidentally.) Modern authors that clearly qualify as frequentists like Bickel, Donoho, Johnstone, or, to mention the French school, e.g., Birgé, Massart, Picard, Tsybakov, none of whom can be suspected of Bayesian inclinations!, do not appear either as satisfying those narrow tenets of frequentism. Furthermore, the concept of frequentist inference is never clearly defined within the paper. As in the above quote, the notion of “legitimate error probabilities” pops up repeatedly (15 times) within the whole manifesto without being explicitely defined. (The closest to a definition is found on page 17, where the significance level and the p-value are found to be legitimate.) Aris Spanos even rejects what I would call the von Mises basis of frequentism: “contrary to Bayesian claims, those error probabilities have nothing to to do with the temporal or the physical dimension of the long-run metaphor associated with repeated samples” (p.17), namely that a statistical  procedure cannot be evaluated on its long term performance… Continue reading →

workshop a Venezia (2)

Posted in pictures, Statistics, Travel, University life with tags , , , , , , , , , , , on October 10, 2012 by xi'an

I could only attend one day of the workshop on likelihood, approximate likelihood and nonparametric statistical techniques with some applications, and I wish I could have stayed a day longer (and definitely not only for the pleasure of being in Venezia!) Yesterday, Bruce Lindsay started the day with an extended review of composite likelihood, followed by recent applications of composite likelihood to clustering (I was completely unaware he had worked on the topic in the 80’s!). His talk was followed by several talks working on composite likelihood and other pseudo-likelihoods, which made me think about potential applications to ABC. During my tutorial talk on ABC, I got interesting questions on multiple testing and how to combine the different “optimal” summary statistics (answer: take all of them, it would not make sense to co;pare one pair with one summary statistic and another pair with another summary statistic), and on why we were using empirical likelihood rather than another pseudo-likelihood (answer: I do not have a definite answer. I guess it depends on the ease with which the pseudo-likelihood is derived and what we do with it. I would e.g. feel less confident to use the pairwise composite as a substitute likelihood rather than as the basis for a score function.) In the final afternoon, Monica Musio presented her joint work with Phil Dawid on score functions and their connection with pseudo-likelihood and estimating equations (another possible opening for ABC), mentioning a score family developped by Hyvärinen that involves the gradient of the square-root of a density, in the best James-Stein tradition! (Plus an approach bypassing the annoying missing normalising constant.) Then, based on a joint work with Nicola Satrori and Laura Ventura, Ruli Erlis exposed a 3rd-order tail approximation towards a (marginal) posterior simulation called HOTA. As Ruli will visit me in Paris in the coming weeks, I hope I can explore the possibilities of this method when he is (t)here. At last, Stéfano Cabras discussed higher-order approximations for Bayesian point-null hypotheses (jointly with Walter Racugno and Laura Ventura), mentioning the Pereira and Stern (so special) loss function mentioned in my post on Måns’ paper the very same day! It was thus a very informative and beneficial day for me, furthermore spent in a room overlooking the Canal Grande in the most superb location!

testing via credible sets

Posted in Statistics, University life with tags , , , , , , , , , , , on October 8, 2012 by xi'an

Måns Thulin released today an arXiv document on some decision-theoretic justifications for [running] Bayesian hypothesis testing through credible sets. His main point is that using the unnatural prior setting mass on a point-null hypothesis can be avoided by rejecting the null when the point-null value of the parameter does not belong to the credible interval and that this decision procedure can be validated through the use of special loss functions. While I stress to my students that point-null hypotheses are very unnatural and should be avoided at all cost, and also that constructing a confidence interval is not the same as designing a test—the former assess the precision in the estimation, while the later opposes two different and even incompatible models—, let us consider Måns’ arguments for their own sake.

The idea of the paper is that there exist loss functions for testing point-null hypotheses that lead to HPD, symmetric and one-sided intervals as acceptance regions, depending on the loss func. This was already found in Pereira & Stern (1999). The issue with these loss functions is that they involve the corresponding credible sets in their definition, hence are somehow tautological. For instance, when considering the HPD set and T(x) as the largest HPD set not containing the point-null value of the parameter, the corresponding loss function is

L(\theta,\varphi,x) = \begin{cases}a\mathbb{I}_{T(x)^c}(\theta) &\text{when }\varphi=0\\ b+c\mathbb{I}_{T(x)}(\theta) &\text{when }\varphi=1\end{cases}

parameterised by a,b,c. And depending on the HPD region.

Måns then introduces new loss functions that do not depend on x and still lead to either the symmetric or the one-sided credible intervals.as acceptance regions. However, one test actually has two different alternatives (Theorem 2), which makes it essentially a composition of two one-sided tests, while the other test returns the result to a one-sided test (Theorem 3), so even at this face-value level, I do not find the result that convincing. (For the one-sided test, George Casella and Roger Berger (1986) established links between Bayesian posterior probabilities and frequentist p-values.) Both Theorem 3 and the last result of the paper (Theorem 4) use a generic and set-free observation-free loss function (related to eqn. (5.2.1) in my book!, as quoted by the paper) but (and this is a big but) they only hold for prior distributions setting (prior) mass on both the null and the alternative. Otherwise, the solution is to always reject the hypothesis with the zero probability… This is actually an interesting argument on the why-are-credible-sets-unsuitable-for-testing debate, as it cannot bypass the introduction of a prior mass on Θ0!

Overall, I furthermore consider that a decision-theoretic approach to testing should encompass future steps rather than focussing on the reply to the (admittedly dumb) question is θ zero? Therefore, it must have both plan A and plan B at the ready, which means preparing (and using!) prior distributions under both hypotheses. Even on point-null hypotheses.

Now, after I wrote the above, I came upon a Stack Exchange page initiated by Måns last July. This is presumably not the first time a paper stems from Stack Exchange, but this is a fairly interesting outcome: thanks to the debate on his question, Måns managed to get a coherent manuscript written. Great! (In a sense, this reminded me of the polymath experiments of Terry Tao, Timothy Gower and others. Meaning that maybe most contributors could have become coauthors to the paper!)