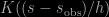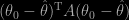I came upon this new book at the Springer booth at JSM 2010. Because its purpose [as stated on the backcover] seemed intriguing enough (“This monograph contributes to the area of comparative statistical inference. Attention is restricted to the important subfield of statistical estimation. (…) The necessary background on Decision Theory and the frequentist and Bayesian approaches to estimation is presented and carefully discussed in Chapters 1–3. The “threshold problem” – identifying the boundary between Bayes estimators which tend to outperform standard frequentist estimators and Bayes estimators which don’t – is formulated in an analytically tractable way in Chapter 4. The formulation includes a specific (decision-theory based) criterion for comparing estimators.“), I bought it and read it during the past month spent travelling through California.
“Robert’s (2001) book, The Bayesian Choice, has similarities to the present work in that the author seeks to determine whether one should be a Bayesian or a frequentist. The main difference between our books is that I come to a different conclusion!” A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
This quote from the preface is admittedly the final reason that made me buy the book by F. Samaniego! When going through the chapters of A comparison of the Bayesian and frequentist approaches to estimation, I found them pleasant to read, written in a congenial (if sometimes repetitive) style, and some places were indeed reminiscent of The Bayesian Choice. However, my overall impression is that this monograph is too inconclusive to attract a large flock of readers and that the two central notions around which the book revolves, namely the threshold between “good and bad priors”, and the self-consistency, are rather weakly supported, at least when seen from my Bayesian perspective.
“Where this [generalised Bayes] approach runs afoul of the laws of coherent Bayesian inference is in its failure to use probability assessments in the qualification of uncertainty”. A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
The book is set within a restrictive setup, which is the Lehmann-Scheffé point estimation framework where there exists one “best” unbiased estimator. Of course, in most estimation problems, there is no unbiased estimator (see Lehmann and Casellla’s Theory of point estimation, for instance). The presentation of the Bayesian principles tends to exclude improper priors as being incoherent (see the above quote) and it calls estimators associated with improper priors generalised Bayes estimators, while I take the alternative stance of calling generalised Bayes estimators those associated with an infinite Bayes risk. (The main appeal of the Bayesian approach, namely to provide all at once a complete inferential machine covering testing as well as estimation aspects, is not covered in the Bayesian chapter.)
“Which method stands to give the “better answers” in real problems of real interest?” A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
The central topic of the book is the comparison of frequentist and Bayesian procedures. Since under a given prior G, the optimal procedure is the Bayesian procedure associated with G and with the loss function, Samaniego introduces a “true prior” G0 to run the comparison between frequentist and Bayesian procedures. The following chapters then revolve around the same type of conclusion: if the prior is close enough to the “true prior” G0 then the Bayesian procedure does better than the frequentist one. Because the conditions for improvement depends on an unknown “truth”, the results are mathematically correct but operationally unappealing: when is one’s prior close enough to the truth? Stating that the threshold separates between “good and bad priors” does not have a strong content, besides the obvious. (From a Bayesian perspective, using the “wrong” prior has been studied for a while in the 1990’s, under the category of Bayesian robustness.)
“Whatever the merits of an objective Bayesian analysis might be, one should recognize that the approach is patently non-Bayesian” A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
The restricted perspective on the Bayesian paradigm is also reflected by the insistence in using conjugate priors and linear estimators. The notion of self-consistency in Chapter 6 does not make sense outside this setting: a prior  on
 is self-consistent if, when
 ,
 .
In other words, if the prior expectation and the observation coincide, the posterior expectation should be the same. This may sound “reasonable” but it only applies to a specific parameterisation of the problem, i.e. is not invariant under reparameterisation of either x or  . It is also essentially restricted to natural conjugate priors, e.g. it does not apply to mixtures of conjugate priors… I also find the relevance of conjugate priors diminished by the following next chapter on shrinkage estimation, since the truly Bayesian shrinkage estimators correspond to hierarchical priors, not to conjugate priors.
“The potential (indeed, typical) lack of consistency of the Bayes estimators of a nonidentifiable parameter need not be considered to be a fatal flaw.” A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
Chapter 9 offers a new perspective on nonidentifiability, but this is highly controversial in that Samaniego’s perspective is to look at the performances of the Bayesian estimates of the nonidentifiable part! While I think the appeal of using a Bayesian approach in non-identifiable settings is instead to be able to infer on the identifiable parts, integrating out the nonidentifiable part thanks to the prior. The chapters 10 and 11 about combining experiments in a vaguely empirical Bayes fashion are more interesting but the proposed solutions sound rather ad hoc. A modern Bayesian analysis would resort to a non-parametric modelling to gather information from past/other experiments.
“But “steadfast” Bayesians and “steadfast” frequentists should also find ample food for thought in these pages” A comparison of the Bayesian and frequentist approaches to estimation, F. Samaniego.
In conclusion, this book recapitulates the works of F. Samaniego and of his co-authors on the frequentist-Bayesian “fusion” into a coherent monograph. I however fear that this treatise cannot contribute to a large extent to the philosophical debate about the relevance of using Bayesian procedures to increase frequentist efficiency or to rely on frequentist estimates when the prior information is shaky. It could appeal to “old timers” from the decision-theoretic creed, but undergraduate and graduate students may find the topic far too narrow and the book too inconclusive to register for a corresponding course. I again agree that decision theory is a nice and reasonable entry into Bayesian analysis, and one that thoroughly got me convinced of following the Bayesian path!, but the final appeal (and hence my Choice)) stems from the universality of the posterior distribution, which covers all aspects of inference.