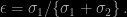Archive for reference priors

Jeffreys prior with improper posterior

Posted in Books, Statistics, University life with tags , , , , , , , , , , on May 12, 2014 by xi'an

In a complete coincidence with my visit to Warwick this week, I became aware of the paper “Inference in two-piece location-scale models with Jeffreys priors” recently published in Bayesian Analysis by Francisco Rubio and Mark Steel, both from Warwick. Paper where they exhibit a closed-form Jeffreys prior for the skewed distribution
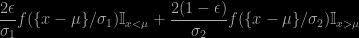
\dfrac{2\epsilon}{\sigma_1}f(\{x-\mu\}/\sigma_1)\mathbb{I}_{x<\mu}+\dfrac{2(1-\epsilon)}{\sigma_2}f(\{x-\mu\}/\sigma_2) \mathbb{I}_{x>\mu}

where f is a symmetric density, namely
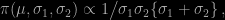
\pi(\mu,\sigma_1,\sigma_2) \propto 1 \big/ \sigma_1\sigma_2\{\sigma_1+\sigma_2\}\,,

where

\epsilon=\sigma_1/\{\sigma_1+\sigma_2\}\,.

only to show  immediately after that this prior does not allow for a proper posterior, no matter what the sample size is. While the above skewed distribution can always be interpreted as a mixture, being a weighted sum of two terms, it is not strictly speaking a mixture, if only because the “component” can be identified from the observation (depending on which side of μ is stands). The likelihood is therefore a product of simple terms rather than a product of a sum of two terms.

As a solution to this conundrum, the authors consider the alternative of the “independent Jeffreys priors”, which are made of a product of conditional Jeffreys priors, i.e., by computing the Jeffreys prior one parameter at a time with all other parameters considered to be fixed. Which differs from the reference prior, of course, but would have been my second choice as well. Despite criticisms expressed by José Bernardo in the discussion of the paper… The difficulty (in my opinion) resides in the choice (and difficulty) of the parameterisation of the model, since those priors are not parameterisation-invariant. (Xinyi Xu makes the important comment that even those priors incorporate strong if hidden information. Which relates to our earlier discussion with Kaniav Kamari on the “dangers” of prior modelling.)

Although the outcome is puzzling, I remain just slightly sceptical of the income, namely Jeffreys prior and the corresponding Fisher information: the fact that the density involves an indicator function and is thus discontinuous in the location μ at the observation x makes the likelihood function not differentiable and hence the derivation of the Fisher information not strictly valid. Since the indicator part cannot be differentiated. Not that I am seeing the Jeffreys prior as the ultimate grail for non-informative priors, far from it, but there is definitely something specific in the discontinuity in the density. (In connection with the later point, Weiss and Suchard deliver a highly critical commentary on the non-need for reference priors and the preference given to a non-parametric Bayes primary analysis. Maybe making the point towards a greater convergence of the two perspectives, objective Bayes and non-parametric Bayes.)

This paper and the ensuing discussion about the properness of the Jeffreys posterior reminded me of our earliest paper on the topic with Jean Diebolt. Where we used improper priors on location and scale parameters but prohibited allocations (in the Gibbs sampler) that would lead to less than two observations per components, thereby ensuring that the (truncated) posterior was well-defined. (This feature also remained in the Series B paper, submitted at the same time, namely mid-1990, but only published in 1994!)  Larry Wasserman proved ten years later that this truncation led to consistent estimators, but I had not thought about it in very long while. I still like this notion of forcing some (enough) datapoints into each component for an allocation (of the latent indicator variables) to be an acceptable Gibbs move. This is obviously not compatible with the iid representation of a mixture model, but it expresses the requirement that components all have a meaning in terms of the data, namely that all components contributed to generating a part of the data. This translates as a form of weak prior information on how much we trust the model and how meaningful each component is (in opposition to adding meaningless extra-components with almost zero weights or almost identical parameters).

As a marginalia, the insistence in Rubio and Steel’s paper that all observations in the sample be different also reminded me of a discussion I wrote for one of the Valencia proceedings (Valencia 6 in 1998) where Mark presented a paper with Carmen Fernández on this issue of handling duplicated observations modelled by absolutely continuous distributions. (I am afraid my discussion is not worth the $250 price tag given by amazon!)

a day for comments

Posted in Mountains, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , on April 21, 2014 by xi'an

As I was flying over Skye (with [maybe] a first if hazy perspective on the Cuillin ridge!) to Iceland, three long sets of replies to some of my posts appeared on the ‘Og:

Thanks to them for taking the time to answer my musings…


Dan Simpson’s seminar at CREST

Posted in Kids, Mountains, Statistics, Travel, University life with tags , , , , , , , , , on April 18, 2014 by xi'an

Daniel Simpson gave a seminar at CREST yesterday on his recently arXived paper, “Penalising model component complexity: A principled, practical  approach to constructing priors” written with Thiago Martins, Andrea Riebler, Håvard Rue, and Sigrunn Sørbye. Paper that he should also have given in Banff last month had he not lost his passport in København airport…  I have already commented at length on this exciting paper, hopefully to become a discussion paper in a top journal!, so I am just pointing out two things that came to my mind during the energetic talk delivered by Dan to our group. The first thing is that those penalised complexity (PC) priors of theirs rely on some choices in the ordering of the relevance, complexity, nuisance level, &tc. of the parameters, just like reference priors. While Dan already wrote a paper on Russian roulette, there is also a Russian doll principle at work behind (or within) PC priors. Each shell of the Russian doll corresponds to a further level of complexity whose order need be decided by the modeller… Not very realistic in a hierarchical model with several types of parameters having only local meaning.

My second point is that the construction of those “politically correct” (PC) priors reflects another Russian doll structure, namely one of embedded models, hence would and should lead to a natural multiple testing methodology. Except that Dan rejected this notion during his talk, by being opposed to testing per se. (A good topic for one of my summer projects, if nothing more, then!)

O’Bayes 2013 [#3]

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , on December 23, 2013 by xi'an

IMG_2223A final day for this O’Bayes 2013 conference, where I missed the final session for travelling reasons. Several talks had highly attractive features (for me), from David Dunson’s on his recently arXived paper on parallel MCMC, that provides an alternative to the embarrassingly parallel algorithm I discussed a few weeks ago, to be discussed further in a future post, to Marty Wells hindered by poor weather and delivering by phone a talk on L1 shrinkage estimators (a bit of a paradox since, as discussed by Yuzo Maruyama, most MAP estimators cannot be minimax and, more broadly, since they cannot be expressed as resolutions of loss minimisation), to Malay Ghosh revisiting g-priors from an almost frequentist viewpoint,  to Gonzalo Garci-Donato presenting criteria for objective Bayesian model choice in a vision that was clearly the closest to my own perspective on the topic. Overall, when reflecting upon the diversity and high quality of the talks at this O’Bayes meeting, and also as the incoming chair-elect of the corresponding section of ISBA, I think that what emerges most significantly from those talks is an ongoing pondering on the nature of (objective Bayesian) testing, not only in the works extending the g-priors in various directions, but also in the whole debate between Bayes factors and information criteria, model averaging versus model selection. During the discussion on Gonzalo’s talk, David Draper objected to the search for an automated approach to the comparison of models, but I strongly lean towards Gonzalo’s perspective as we need to provide a reference solution able to tackle less formal and more realistic problems. I do hope to see more of those realistic problems tackled at O’Bayes 2015 (which location is not yet settled). In the meanwhile, a strong thank you! to the local organising committee and most specifically to Jim Berger!

O’Bayes 2013 [#2]

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , on December 19, 2013 by xi'an

IMG_2193Another day at O’Bayes 2013, recovering from the flow of reminiscences of yesterday. Talks from Guido Consonni on running reference model selection in complex designs, from Dimitris Fouskakis on integrating out imaginary observations in a g-prior, which seems to bring more sparsity than the hyper-g prior in variable selection, from François Perron on Bayesian inference for copulas, with an innovative parametrisation and links with Polya trees, from Nancy Reid and Laura Ventura on likelihood approximations and pseudo-likelihoods, offering a wide range of solutions for ABC (or BC) references (with the lingering question of the validation of the approximation for a given sample, as discussed by Brunero Liseo) and from two physicists to conclude the day! Tomorrow is the final day and I hope I can go running a last time in the woods before the flights back to Paris.