 I had a wonderful time in CMU, talking with a lot of faculty about their research (and mine), like reminiscing of things past and expanding on things to come with Larry (not to mention exchanging blogging impressions), giving my seminar talk, having a great risotto at Casbah, and a nice dinner at Legume, going for morning runs in the nearby park… One particularly memorable moment was the discussion I had with Jay as/since he went back to our diverging views about objective Bayes and improper priors, as expressed in the last chapter of his book and my review of it. While we kept disagreeing on their relevance and on whether or not they should be used, I had to concede that one primary reason for using reference priors is one of laziness in not seeking expert opinions. Even though there always is a limit to the information provided by such experts that means a default input at one level or the next (of a hierarchical model). Jay also told me of his proposal (as reported in his 1996 Bayesian methods and ethics in a clinical trial design book) for conducting clinical trials with several experts (with different priors) and sequentially weighting them by their predictive success. Proposal which made me think of a sequential way to compare models by their predictive abilities and still use improper priors…
Archive for reference priors
a talk with Jay
Posted in Books, Running, Statistics, Travel, University life with tags Bayesian model choice, Carnegie Mellon University, Casbah, CMU, improper priors, Normal deviate, objective Bayes, Pennsylvania, Pittsburgh, reference priors, subjective versus objective Bayes on November 1, 2013 by xi'anwhetstone and alum block for Occam’s razor
Posted in Statistics, University life with tags alum, Bayes factor, Bayesian model choice, moment prior, Ockham's razor, reference priors, whetstone on August 1, 2013 by xi'an
A strange title, if any! (The whetstone is a natural hard stone used for sharpening steel instruments, like knifes or sickles and scythes, I remember my grand-fathers handling one when cutting hay and weeds. Alum is hydrated potassium aluminium sulphate and is used as a blood coagulant. Both items are naturally related with shaving and razors, if not with Occam!) The whole title of the paper published by Guido Consonni, Jon Forster and Luca La Rocca in Statistical Science is “The whetstone and the alum block: balanced objective Bayesian comparison of nested models for discrete data“. The paper builds on the notions introduced in the last Valencia meeting by Guido and Luca (and discussed by Judith Rousseau and myself).
Beyond the pun (that forced me to look for “alum stone” on Wikipedia!, and may be lost on some other non-native readers), the point in the title is to build a prior distribution aimed at the comparison of two models such that those models are more sharply distinguished: Occam’s razor would thus cut better when the smaller model is true (hence the whetstone) and less when it is not (hence the alum block)… The solution proposed by the authors is to replace the reference prior on the larger model, π1, with a moment prior à la Johnson and Rossell (2010, JRSS B) and then to turn this moment prior into an intrinsic prior à la Pérez and Berger (2002, Biometrika), making it an “intrinsic moment”. The first transform turns π1 into a non-local prior,
 with the aim of correcting for the imbalanced convergence rates of the Bayes factor under the null and under the alternative (this is the whetstone). The second transform accumulates more mass in the vicinity of the null model (this is the alum block). (While I like the overall perspective on intrinsic priors, the introduction is a wee confusing about them, e.g. when it mentions fictive observations instead of predictives.)
Being a referee for this paper, I read it in detail (and also because this is one of my favourite research topics!) Further, we already engaged into a fruitful discussion with Guido since the last Valencia meeting and the current paper incorporates some of our comments (and replies to others). I find the proposal of the authors clever and interesting, but not completely Bayesian. Overall, the paper provides a clearly novel methodology that calls for further studies…
a general framework for updating belief functions [reply from the authors]
Posted in Statistics, University life with tags Bayesian foundations, Bayesian inference, decision theory, loss functions, reference priors, Royal Statistical Society, RSS on July 16, 2013 by xi'anHere is the reply by Chris and Steve about my comments from yesterday:
Thanks to Christian for the comments and feedback on our paper “A General Framework for Updating Belief Distributions“. We agree with Christian that starting with a summary statistic, or statistics, is an anchor for inference or learning, providing direction and guidance for models, avoiding the alternative vague notion of attempting to model a complete data set. The latter idea has dominated the Bayesian methodology for decades, but with the advent of large and complex data sets, this is becoming increasingly challenging, if not impossible.
However, in order to do work with statistics of interest, we need to find a framework in which this direct approach can be supported by a learning strategy when the formal use of Bayes theorem is not applicable. We achieve this in the paper for a general class of loss functions, which connect observations with a target of interest. A point raised by Christian is how arbitrary these loss functions are. We do not see this at all; for if a target has been properly identified then the most primitive construct between observations informing about a target and the target would come in the form of a loss function. One should always be able to assess the loss of ascertaining a value of 
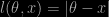
or subjective, in the case of the choice between loss functions for estimating a location of a distribution; mean, median or mode? But our work is situated in the former position.
Previous work on loss functions, mostly in the classical literature, has spent a lot of space working out what are optimal loss functions for targets of interest. We are not really dealing with novel targets and so we can draw on the classic literature here. The work can be thought of as the Bayesian version of the M-estimator and associated ideas. In this respect we are dealing with two loss functions for updating belief distributions, one for the data, which we have just discussed, and one for the prior information, which, due to coherence principles, must be the Kullback-Leibler divergence. This raises the thorny issue of how to calibrate the two loss functions. We discuss this in the paper.
To then deal with the statistic problem, mentioned at the start of this discussion, we have found a nice way to proceed by using the loss function 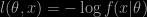

is provided in the Walker talk at Bayes 250 in London, titled “The Misspecified Bayesian”, since the “model” 

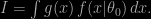
This is the story of the background, we would now like to pick up in more detail on three important points that you raise in your post:
- The arbitrariness in selecting the loss function.
- The relative weighting of loss-to-data vs. loss-to-prior.
- The selection of the loss in the M-free case.
In the absence of complete knowledge of the data generating mechanism, i.e. outside of M-closed,
- We believe the statistician should weigh up the relative arbitrariness in selecting a loss function targeting the statistic of interest versus the arbitrariness of selecting a misspecified model, known not to be true, for the complete data generating mechanism. There is a wealth of literature on how to select optimal loss functions that target specific statistics, e.g. Hüber (2009) provides a comprehensive overview of how this should be done. As far as we are aware, we know of no formal procedures (that do not rely on loss functions) to select a false sampling distribution
- The relative weighting of loss-to-data vs. loss-to-prior. This is an interesting open problem. Our framework shows in the absence of M-closed or the use of self-information loss that the analyst must select this weighting. In our paper we suggest some default procedures. We have nowhere claimed these were “correct”. You raise concerns regards parameterisation and we agree with you that care is needed, but many of these issues equally hold for existing “Objective” or “Default” Bayes procedures, such as unit-information priors.
- The selection of the loss in M-free. You say “….there is no optimal choice for the substitute to the loss function…”. We disagree. Our approach is to select an established loss function that directly targets the statistic of interest, and elicit prior beliefs directly on the unknown value of this statistic. There is no notion here of a a pseudo-likelihood or where this converges to.
Thank you again to Christian for his critical observations!
Error and Inference [#5]
Posted in Books, Statistics, University life with tags Bayesian inference, book review, Error-Statistical philosophy, frequentist inference, improper priors, Likelihood Principle, Neyman-Pearson, reference priors, statistical inference, Sufficiency principle, testing of hypotheses, The Bayesian Choice, weak conditionality principle on September 28, 2011 by xi'an(This is the fifth post on Error and Inference, as previously being a raw and naïve reaction following a linear and slow reading of the book, rather than a deeper and more informed criticism.)
“‘Frequentist methods achieve an objective connection to hypotheses about the data-generating process by being constrained and calibrated by the method’s error probabilities in relation to these models .”—D. Cox and D. Mayo, p.277, Error and Inference, 2010
The second part of the seventh chapter of Error and Inference, is David Cox’s and Deborah Mayo’s “Objectivity and conditionality in frequentist inference“. (Part of the section is available on Google books.) The purpose is clear and the chapter quite readable from a statistician’s perspective. I however find it difficult to quantify objectivity by first conditioning on “a statistical model postulated to have generated data”, as again this assumes the existence of a “true” probability model where “probabilities (…) are equal or close to the actual relative frequencies”. As earlier stressed by Andrew:
“I don’t think it’s helpful to speak of “objective priors.” As a scientist, I try to be objective as much as possible, but I think the objectivity comes in the principle, not the prior itself. A prior distribution–any statistical model–reflects information, and the appropriate objective procedure will depend on what information you have.”

The paper opposes the likelihood, Bayesian, and frequentist methods, reproducing what Gigerenzer called the “superego, the ego, and the id” in his paper on statistical significance. Cox and Mayo stress from the start that the frequentist approach is (more) objective because it is based on the sampling distribution of the test. My primary problem with this thesis is that the “hypothetical long run” (p.282) does not hold in realistic settings. Even in the event of a reproduction of similar or identical tests, a sequential procedure exploiting everything that has been observed so far is more efficient than the mere replication of the same procedure solely based on the current observation.
“Virtually all (…) models are to some extent provisional, which is precisely what is expected in the building up of knowledge.”—D. Cox and D. Mayo, p.283, Error and Inference, 2010
The above quote is something I completely agree with, being another phrasing of George Box’s “all models are wrong”, but this transience of working models is a good reason in my opinion to account for the possibility of alternative working models from the start of the statistical analysis. Hence for an inclusion of those models in the statistical analysis equally from the start. Which leads almost inevitably to a Bayesian formulation of the testing problem.
“‘Perhaps the confusion [over the role of sufficient statistics] stems in part because the various inference schools accept the broad, but not the detailed, implications of sufficiency.”—D. Cox and D. Mayo, p.286, Error and Inference, 2010
The discussion over the sufficiency principle is interesting, as always. The authors propose to solve the confusion between the sufficiency principle and the frequentist approach by assuming that inference “is relative to the particular experiment, the type of inference, and the overall statistical approach” (p.287). This creates a barrier between sampling distributions that avoids the binomial versus negative binomial paradox always stressed in the Bayesian literature. But the solution is somehow tautological: by conditioning on the sampling distribution, it avoids the difficulties linked with several sampling distributions all producing the same likelihood. After my recent work on ABC model choice, I am however less excited about the sufficiency principle as the existence of [non-trivial] sufficient statistics is quite the rare event. Especially across models. The section (pp. 288-289) is also revealing about the above “objectivity” of the frequentist approach in that the derivation of a test taking large value away from the null with a well-known distribution under the null is not an automated process, esp. when nuisance parameters cannot be escaped from (pp. 291-294). Achieving separation from nuisance parameters, i.e. finding statistics that can be conditioned upon to eliminate those nuisance parameters, does not seem feasible outside well-formalised models related with exponential families. Even in such formalised models, a (clear?) element of arbitrariness is involved in the construction of the separations, which implies that the objectivity is under clear threat. The chapter recognises this limitation in Section 9.2 (pp.293-294), however it argues that separation is much more common in the asymptotic sense and opposes the approach to the Bayesian averaging over the nuisance parameters, which “may be vitiated by faulty priors” (p.294). I am not convinced by the argument, given that the (approximate) condition approach amount to replace the unknown nuisance parameter by an estimator, without accounting for the variability of this estimator. Averaging brings the right (in a consistency sense) penalty.
 A compelling section is the one about the weak conditionality principle (pp. 294-298), as it objects to the usual statement that a frequency approach breaks this principle. In a mixture experiment about the same parameter θ, inferences made conditional on the experiment “are appropriately drawn in terms of the sampling behavior in the experiment known to have been performed” (p. 296). This seems hardly objectionable, as stated. And I must confess the sin of stating the opposite as The Bayesian Choice has this remark (Example 1.3.7, p.18) that the classical confidence interval averages over the experiments… Mea culpa! The term experiment validates the above conditioning in that several experiments could be used to measure θ, each with a different p-value. I will not argue with this. I could however argue about “conditioning is warranted to achieve objective frequentist goals” (p. 298) in that the choice of the conditioning, among other things, weakens the objectivity of the analysis. In a sense the above pirouette out of the conditioning principle paradox suffers from the same weakness, namely that when two distributions characterise the same data (the mixture and the conditional distributions), there is a choice to be made between “good” and “bad”. Nonetheless, an approach based on the mixture remains frequentist if non-optimal… (The chapter later attacks the derivation of the likelihood principle, I will come back to it in a later post.)
“‘Many seem to regard reference Bayesian theory to be a resting point until satisfactory subjective or informative priors are available. It is hard to see how this gives strong support to the reference prior research program.”—D. Cox and D. Mayo, p.302, Error and Inference, 2010
A section also worth commenting is (unsurprisingly!) the one addressing the limitations of the Bayesian alternatives (pp. 298–302). It however dismisses right away the personalistic approach to priors by (predictably if hastily) considering it fails the objectivity canons. This seems a wee quick to me, as the choice of a prior is (a) the choice of a reference probability measure against which to assess the information brought by the data, not clearly less objective than picking one frequentist estimator or another, and (b) a personal construction of the prior can also be defended on objective grounds, based on the past experience of the modeler. That it varies from one modeler to the next is not an indication of subjectivity per se, simply of different past experiences. Cox and Mayo then focus on reference priors, à la Bernardo-Berger, once again pointing out the lack of uniqueness of those priors as a major flaw. While the sub-chapter agrees on the understanding of those priors as convention or reference priors, aiming at maximising the input from the data, it gets stuck on the impropriety of such priors: “if priors are not probabilities, what then is the interpretation of a posterior?” (p.299). This seems like a strange comment to me: the interpretation of a posterior is that it is a probability distribution and this is the only mathematical constraint one has to impose on a prior. (Which may be a problem in the derivation of reference priors.) As detailed in The Bayesian Choice among other books, there are many compelling reasons to invite improper priors into the game. (And one not to, namely the difficulty with point null hypotheses.) While I agree that the fact that some reference priors (like matching priors, whose discussion p. 302 escapes me) have good frequentist properties is not compelling within a Bayesian framework, it seems a good enough answer to the more general criticism about the lack of objectivity: in that sense, frequency-validated reference priors are part of the huge package of frequentist procedures and cannot be dismissed on the basis of being Bayesian. That reference priors are possibly at odd with the likelihood principle does not matter very much: the shape of the sampling distribution is part of the prior information, not of the likelihood per se. The final argument (Section 12) that Bayesian model choice requires the preliminary derivation of “the possible departures that might arise” (p.302) has been made at several points in Error and Inference. Besides being in my opinion a valid working principle, i.e. selecting the most appropriate albeit false model, this definition of well-defined alternatives is mimicked by the assumption of “statistics whose distribution does not depend on the model assumption” (p. 302) found in the same last paragraph.
In conclusion this (sub-)chapter by David Cox and Deborah Mayo is (as could be expected!) a deep and thorough treatment of the frequentist approach to the sufficiency and (weak) conditionality principle. It however fails to convince me that there exists a “unique and unambiguous” frequentist approach to all but the most simple problems. At least, from reading this chapter, I cannot find a working principle that would lead me to this single unambiguous frequentist procedure.
València 9 snapshot [5]
Posted in pictures, Running, Statistics, University life with tags Benidorm, decision theory, intrinsic losses, Lasso, latent variable, reference priors, sparsity, Valencia 9 on June 9, 2010 by xi'an For the final day of the meeting, after a good one hour run to the end of the Benidorm bay (for me at least!), we got treated to great talks, culminating with the fitting conclusion given by the conference originator, José Bernardo. The first talk of the day was Guido Consonni’s, who introduced a new class of non-local priors to deal with variable selection. From my understanding, those priors avoid a neighbourhood of zero by placing a polynomial prior on the regression coefficients in order to discriminate better between the null and the alternative,

but the influence of the power h seems to be drastic, judging from the example showed by Guido where a move from h=0 to h=1, modified the posterior probability from 0.091 to 0.99 for the same dataset. The discussion by Jim Smith was a perfect finale to the Valencia meetings, Jim being much more abrasive than the usual discussant (while always giving the impression of being near a heart attack//!) The talk from Sylvia Früwirth-Schnatter purposely borrowed Nick Polson’ s title Shrink globally, act locally, and was also dealing with the Bayesian (re)interpretation of Lasso. (I was again left with the impression of hyperparameters that needed to be calibrated but this impression may change after I read the paper!) The talk by Xiao-Li Meng was as efficient as ever with Xiao-Li! Despite the penalising fact of being based on a discussion he wrote for Statistical Science, he managed to convey a global and convincing picture of likelihood inference in latent variable models, while having the audience laugh most of the talk, a feat repeated by his discussant, Ed George. The basic issue of treating latent variables as parameters offers no particular difficulty in Bayesian inference but this is not true for likelihood models, as shown by both Xiao-Li and Ed. The last talk of the València series managed to make a unifying theory out of the major achievements of José Bernardo and, while I have some criticisms about the outcome, this journey back to decision theory, intrinsic losses and reference priors was nonetheless a very appropriate supplementary contribution of José to this wonderful series of meetings…. Luis Perricchi discussed the paper in a very opinionated manner, defending the role of the Bayes factor, and the debate could have gone forever…Hopefully, I will find time to post my comments on José’s paper.

I am quite sorry I had to leave before the Savage prize session where the four finalists to the prize gave a lecture. Those finalists are of the highest quality as the prize is not given in years when the quality of the theses is not deemed high enough. I will also miss the final evening during which the DeGroot Prize is attributed. (When I received the prize for Bayesian Core. in 2004, I had also left in the morning Valparaiso, just before the banquet!)


