Archive for revision

mad statistic

Posted in R, Statistics, University life with tags , , , , , on April 30, 2012 by xi'an

In the motivating toy example to our ABC model choice paper, we compare summary statistics, mean, median, variance, and… median absolute deviation (mad). The latest is the only one able to discriminate between our normal and Laplace models (as now discussed on Cross Validated!). When rerunning simulations to produce nicer graphical outcomes (for the revision), I noticed a much longer run time associated with the computation of the mad statistic. Here is a comparison for the computation of the mean, median, and mad on identical simulations:

[sourcecode language=”r” gutter=”false”]
> system.time(mmean(10^5))
user system elapsed
4.040 0.056 4.350
> system.time(mmedian(10^5))
user  system elapsed
12.509   0.012  15.353
> system.time(mmad(10^5))
user system elapsed
23.345 0.036 23.458
[/sourcecode]

Now, this is not particularly surprising: computing a median takes longer than computing a mean, even using quicksort!, hence computing two medians… Still, having to wait about six times longer for the delivery of a mad statistics is somehow…mad!

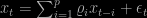
Checking for stationarity [X-valid’ed]

Posted in Books, Statistics, University life with tags , , , , , , , , on January 16, 2012 by xi'an

While working with Jean-Michel Marin on the revision of Bayesian Core, and more specifically on the time series chapter, I was wondering about the following problem:

It is well-known [at least to readers of  Bayesian Core] that an AR(p) process

x_t=\sum_{i=1}^p \varrho_i x_{t-i} + \epsilon_t

is causal and stationary if and only if the roots of the polynomial

\mathcal{P}(u) = 1 - \sum_{i=1}^p \varrho_i u^i

are all outside the unit circle in the complex plane. This defines an implicit (and unfriendly!) parameter space for the original parameters of the AR(p) model. In particular, when considering a candidate parameter, to determine whether or not the constraint is satisfied implies checking for the root of the associated polynomial. The question  I asked on Cross Validated a few days ago was whether or not there existed a faster algorithm than the naïve one that consists in (a) finding the roots of P and (b) checking none one them is inside the unit circle. Two hours later I got a reply from J. Bowman about the Schur-Cohn procedure that answers the question about the roots in O(p²) steps without going through the determination of the roots. (This is presumably the same Issai Schur as in Schur’s lemma.) However,  J. Bowman also pointed out that the corresponding order for polynomial root solvers is O(p²)! Nonetheless, I think the Schur-Cohn procedure is way faster.

Bayesian variable selection [off again]

Posted in Statistics, University life with tags , , , , , , on November 16, 2011 by xi'an

As indicated a few weeks ago, we have received very encouraging reviews from Bayesian Analysis about our [Gilles Celeux, Mohammed El Anbari, Jean-Michel Marin and myself] our comparative study of Bayesian and non-Bayesian variable selections procedures (“Regularization in regression: comparing Bayesian and frequentist methods in a poorly informative situation“) to Bayesian Analysis. We have just  rearXived and resubmitted it with additional material and hope this is the last round. (I must acknowledge a limited involvement at this final stage of the paper. Had I had more time available, I would have liked to remove the numerous tables and turn them into graphs…)

Bayesian Core and loose logs

Posted in Books, R, Statistics, University life with tags , , , , on July 26, 2011 by xi'an

Jean-Michel (aka Jean-Claude!) Marin came for a few days so that we could make late progress on the revision of our book Bayesian Core towards an Use R! version. In one of the R programs in the mixture chapter, we were getting improbable answers, until we found an R mistake in the shape of

[sourcecode language=”r” gutter=”false”]
> sum(c(1,2,3,log=TRUE))
[1] 7
> sum(c(1,2,3),log=TRUE)
[1] 7
[/sourcecode]

which was not detected by the compiler… There are surely plenty of good reasons for this to happen and it did not take long to fix the bug, still… annoying!

Questions on ABC

Posted in Statistics, University life with tags , , , , , , on May 31, 2011 by xi'an

Our ABC survey for Statistics and Computing (and the ABC special issue!) has been quickly revised, resubmitted, and rearXived. Here is our conclusion about some issues that remain unsolved (much more limited in scope than the program drafted by Halton!):

  1. the convergence results obtained so far are unpractical in that they require either the tolerance to go to zero or the sample size to go to infinity. Obtaining exact error bounds for positive tolerances and finite sample sizes would bring a strong improvement in both the implementation of the method and in the assessment of its worth.
  2. in particular, the choice of the tolerance is so far handled from a very empirical perspective. Recent theoretical assessments show that a balance between Monte Carlo variability and target approximation is necessary, but the right amount of balance must be reached towards a practical implementation.
  3.  even though ABC is often presented as a converging method that approximates Bayesian inference, it can also be perceived as an inference technique per se and hence analysed in its own right. Connections with indirect inference have already been drawn, however the fine asymptotics of ABC would be most useful to derive. Moreover, it could indirectly provide indications about the optimal calibration of the algorithm.
  4. in connection with the above, the connection of ABC-based inference with other approximative methods like variational Bayes inference is so far unexplored. Comparing and interbreeding those different methods should become a research focus as well.
  5. the construction and selection of the summary statistics is so far highly empirical. An automated approach based on the principles of data analysis and approximate sufficiency would be much more attractive and convincing, especially in non-standard and complex settings. \item the debate about ABC-based model choice is so far inconclusive in that we cannot guarantee the validity of the approximation, while considering that a “large enough” collection of summary statistics provides an acceptable level of approximation. Evaluating the discrepancy by exploratory methods like the bootstrap would shed a much more satisfactory light on this issue.
  6.  the method necessarily faces limitations imposed by large datasets or complex models, in that simulating pseudo-data may itself become an impossible task. Dimension-reducing techniques that would simulate directly the summary statistics will soon become necessary.